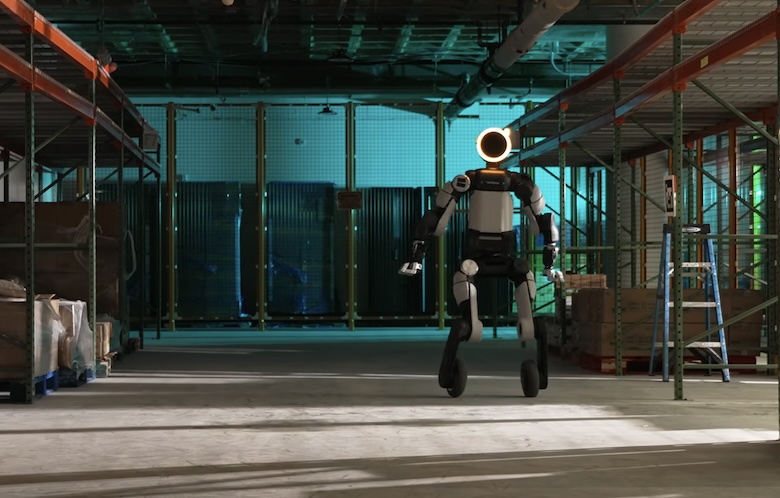
Physical Intelligence published research on RL tokens (RLT), a method for rapidly adapting vision-language-action (VLA) models to improve precision-critical manipulation tasks. The system trains a small reinforcement learning policy on top of a frozen VLA using a compressed representation called an RL token, which summarizes the model's internal state. Training occurs directly on the robot in real time, with hundreds of updates per second.
The approach targets the hardest phase of manipulation tasks—contact-rich moments requiring sub-millimeter precision. In the screwdriver task, the robot must align a screw tip with an M3 screw hole while accounting for positional errors amplified by a 10cm lever arm from the grasp point. The base VLA handles coarse motions well but struggles with fine alignment. RLT isolates and improves exactly this phase.
Physical Intelligence evaluated RLT on four tasks: electric screwdriver operation, zip tie fastening, Ethernet cable insertion, and power cord plugging. The RL-trained model improved throughput (successful completions per 10 minutes) substantially across all tasks. On Ethernet insertion, training took two hours total with only 15 minutes of active robot data. The final policy's median execution time was 66 timesteps versus 146 for human teleoperation and 228 for the base model—a 3× speed improvement over the base and faster than human operators.
The method uses action chunking to match the VLA's temporal structure, regularizes updates toward the VLA's reference actions to limit exploration, and incorporates human interventions directly into the RL loop when the robot fails. These design choices make RLT a reusable recipe attachable to pretrained VLAs without task-specific tuning.
The research builds on Physical Intelligence's earlier Recap algorithm, which focused on large-scale, long-horizon RL. RLT complements that work by enabling fine-grained, rapid adaptation of individual skills during deployment—a step toward robots that improve on the job.